Oliver Crawl
A reusable web-crawling library designed to collect information safely, avoid unnecessary processing, and keep recurring data pipelines efficient.
The problem
Collecting a web page is straightforward. Running a crawler repeatedly, across many sources, introduces more complicated problems.
A reliable crawler needs to handle unsafe destinations, redirects, changing pages, unreliable sources, and the cost of processing information that hasn't changed.
The approach
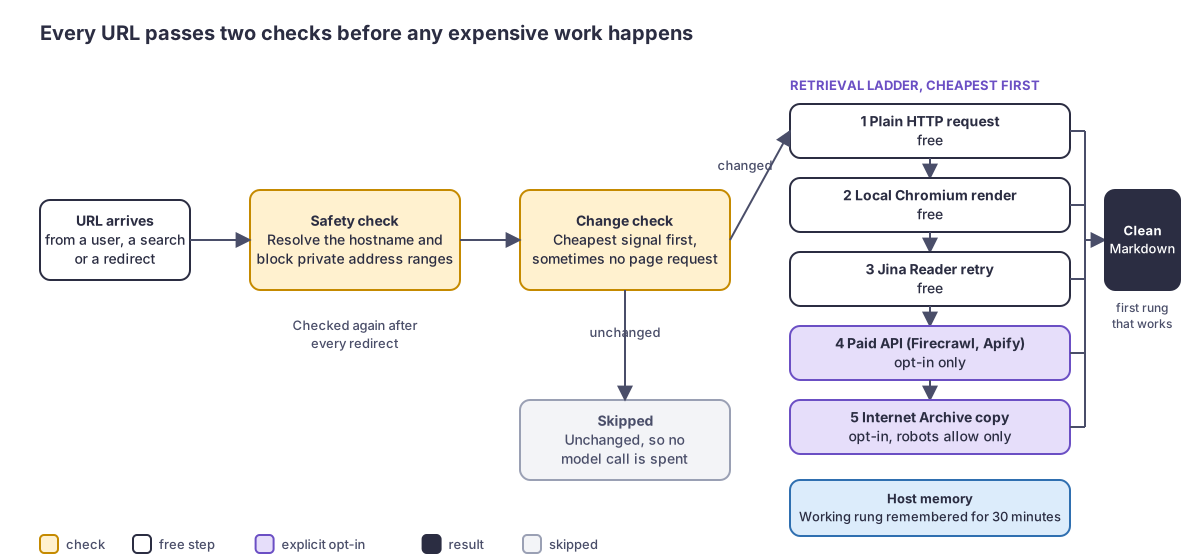
- Safe collection. The crawler checks destinations throughout the request process to prevent requests from reaching protected internal resources
- Change-aware processing. Pages that haven't changed can be skipped before more expensive downstream processing begins
- Efficient retrieval. It tries simpler, lower-cost collection methods before escalating to more involved ones
- Explicit cost controls. Paid services require deliberate configuration and approval, and are never silently invoked
- Flexible source handling. Different retrieval methods are available for different source types, with appropriate restrictions
- Reusable behavior. The library remembers recent successful approaches to make recurring collection more efficient
The result
A versioned, reusable library that works without requiring an API key or account for its default functionality. It supports Node.js and edge and serverless environments, and powers web collection within Fallow.
Stack
TypeScript, Node 20+, Playwright for local rendering, Vitest.
Evidence
Powers web collection within Fallow, and enforces its safety and cost rules with automated checks that fail the build.
Links
Source: oliver-chase/oliver-crawl.